JMP Security Notice: CVE-2026-109618 and CVE-2026-109619
JMP promptly initiated a review of its products, services, and relevant infrastructure for exposure to CVE-2026-109618 and CVE-2026-109619.
Our assessment of JMP products has not identified exposure to these vulnerabilities. Where remediation was required within supporting environments, appropriate security updates and controls have been applied and validated.
We have identified no evidence of successful exploitation or unauthorized access to JMP systems or customer information associated with these vulnerabilities.
JMP continues to monitor the issue and relevant vendor guidance. No action is required by JMP customers at this time.
- Don’t miss your chance to experience Discovery Summit Europe at our best available rate! Early bird registration through 31 Oct.
- Graph Builder Toolbar streamlines interactive graphing. Creates shortcuts on Report and GraphBuilder Helpers toolbars. Download and install the extension.
- Subscribe to RSS Feed
- Mark Topic as New
- Mark Topic as Read
- Float this Topic for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Discussions
Solve problems, and share tips and tricks with other JMP users.- User Community
- :
- Discussions
- :
- Re: Filter the most frequent value in multiple columns
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Filter the most frequent value in multiple columns
Hi everyone,
My goal is to select only the rows that have the most common values (character type) in each column.
For instance, my table has four columns: A, B, C, and D. The values that appear the most in columns A, B, C, and D are A1, B2, C3, and D4, respectively. How can I write a JSL code that filters the rows by these values and creates a new table with the filtered data? Thank you.
Thanks
Accepted Solutions


- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Filter the most frequent value in multiple columns
Here is a script that should give you a leg up in solving your issue
Names Default To Here( 1 );

// build an example data table
dt = New Table( "Example",
	add rows( 20 ),
	New Column( "A",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 40, x = 1,
				rand >= 40 & rand <= 60, x = 2,
				rand >= 60 & rand <= 80, x = 3,
				x = 4
			);
			"A" || Char( x );
		)
	),
	New Column( "B",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 60, x = 2,
				rand >= 60 & rand <= 80, x = 3,
				x = 4
			);
			"B" || Char( x );
		)
	),
	New Column( "C",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 40, x = 2,
				rand >= 40 & rand <= 80, x = 3,
				x = 4
			);
			"C" || Char( x );
		)
	),
	New Column( "D",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 40, x = 2,
				rand >= 40 & rand <= 60, x = 3,
				x = 4
			);
			"D" || Char( x );
		)
	)
);


// The JSL below is the code that does the actual work
Data Table( "Example" ) << Stack(
	columns( :A, :B, :C, :D ),
	Source Label Column( "Column" ),
	Stacked Data Column( "Data" ),
	Output Table( "Stacked" )
);

dtS = Data Table( "Stacked" ) << Summary(
	Group( :Column, :Data ),
	Freq( "None" ),
	Weight( "None" ),
	output table name( "Summary" )
);

dtS << select where( :N Rows[Row()] == col max(:N Rows, :Data));
dtS << new column("Mode", formula(
	Col Max(:N Rows, :Column)
));
dtS << select where( :N Rows == :Mode);
dtS << invert row selection << delete rows;

eval(parse(
"dt << Select Where (dt:\!"" || dts:column[1]  || "\!"n == dtS:Data[1] );"));

For( i=2,i<=NRows(dtS), i++,
	eval(parse(
	"dt << Select Where (dt:\!"" || dts:column[i]  || "\!"n == dtS:Data[i] , current selection(\!"extend\!"));"));
);

dtFinal = dt << Subset( selected columns(0), selected rows(1), output table("Final"));
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Filter the most frequent value in multiple columns
If you had data like this where (COL -> Most appearances) is A -> A1, B -> B2, C -> C1 (in reality C has a tie, how should these be handled?)
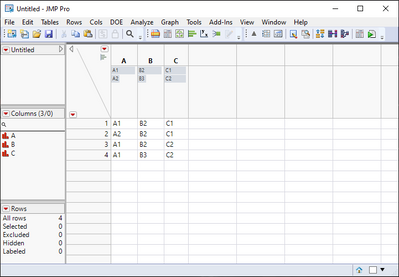
Would you wish to only keep row1 as it has A1, B2 and C1? And if there were more rows with the same values, would you want to keep them all? Or are you looking for something totally different, for example do you want to have a table which just has the values which appear the most?
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Filter the most frequent value in multiple columns
Here is a script that should give you a leg up in solving your issue
Names Default To Here( 1 );

// build an example data table
dt = New Table( "Example",
	add rows( 20 ),
	New Column( "A",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 40, x = 1,
				rand >= 40 & rand <= 60, x = 2,
				rand >= 60 & rand <= 80, x = 3,
				x = 4
			);
			"A" || Char( x );
		)
	),
	New Column( "B",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 60, x = 2,
				rand >= 60 & rand <= 80, x = 3,
				x = 4
			);
			"B" || Char( x );
		)
	),
	New Column( "C",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 40, x = 2,
				rand >= 40 & rand <= 80, x = 3,
				x = 4
			);
			"C" || Char( x );
		)
	),
	New Column( "D",
		character,
		formula(
			rand = Random Uniform( 0, 100 );
			If(
				rand >= 0 & rand <= 20, x = 1,
				rand >= 20 & rand <= 40, x = 2,
				rand >= 40 & rand <= 60, x = 3,
				x = 4
			);
			"D" || Char( x );
		)
	)
);


// The JSL below is the code that does the actual work
Data Table( "Example" ) << Stack(
	columns( :A, :B, :C, :D ),
	Source Label Column( "Column" ),
	Stacked Data Column( "Data" ),
	Output Table( "Stacked" )
);

dtS = Data Table( "Stacked" ) << Summary(
	Group( :Column, :Data ),
	Freq( "None" ),
	Weight( "None" ),
	output table name( "Summary" )
);

dtS << select where( :N Rows[Row()] == col max(:N Rows, :Data));
dtS << new column("Mode", formula(
	Col Max(:N Rows, :Column)
));
dtS << select where( :N Rows == :Mode);
dtS << invert row selection << delete rows;

eval(parse(
"dt << Select Where (dt:\!"" || dts:column[1]  || "\!"n == dtS:Data[1] );"));

For( i=2,i<=NRows(dtS), i++,
	eval(parse(
	"dt << Select Where (dt:\!"" || dts:column[i]  || "\!"n == dtS:Data[i] , current selection(\!"extend\!"));"));
);

dtFinal = dt << Subset( selected columns(0), selected rows(1), output table("Final"));
Recommended Articles
- © 2026 JMP Statistical Discovery LLC. All Rights Reserved.
- Terms of Use
- Privacy Statement
- Contact Us