Turn on suggestions
Auto-suggest helps you quickly narrow down your search results by suggesting possible matches as you type.
- Don’t miss your chance to experience Discovery Summit Europe at our best available rate! Early bird registration through 31 Oct.
- Graph Builder Toolbar streamlines interactive graphing. Creates shortcuts on Report and GraphBuilder Helpers toolbars. Download and install the extension.
- JMP will suspend normal business operations for our Rest and Recharge Day on Friday, October 2, 2026.
Regular business hours will resume on Monday, October 5, 2026.
Options
- Subscribe to RSS Feed
- Mark Topic as New
- Mark Topic as Read
- Float this Topic for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Discussions
Solve problems, and share tips and tricks with other JMP users.- User Community
- :
- Discussions
- :
- Delete consecutive repeating values
Level I
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Delete consecutive repeating values
Jul 28, 2023 09:24 AM
(2188 views)
I have a data table where some of the columns have values that repeat because the program that generates the data holds the last value if a new one isn't given. This means I can't use the "select duplicate rows" option because that deletes all duplicates not just ones that are repeating. I also don't want to delete the rows, just the values in the "cells".
- 4.1
- 3.4
- 3.4 - delete value
- 3.4 - delete value
- 5.1
- 2.6
- 4.1 - keep!
- 3.4 - keep!
- 7.2
- 7.2 - delete value
- 7.2 - delete value
This would become
- 4.1
- 3.4
- .
- .
- 5.1
- 2.6
- 4.1
- 3.4
- 7.2
- .
- .
JMP Pro 17.0.0
2 REPLIES 2

Level VI
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Delete consecutive repeating values
Vous pouvez utiliser un script comme ci-dessous :
Names Default To here(1);

dt= current data table();

// nouvelle colonne
dt << New Column( "nouvelles valeurs",
	Numeric,
	"Continuous",
	Format( "Best", 12 )
);


// Modifier la formule de colonne : nouvelles valeurs
dt:nouvelles valeurs <<
Set Formula(
	If( :valeurs[Sequence( 1, N rows(dt), 1, 1 )] == :valeurs[Sequence( 2, N rows(dt), 1, 1 )],
		:nouvelles valeurs = .,
		:nouvelles valeurs = :valeurs
	)
);

Super User
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Delete consecutive repeating values
I would most likely use either Dif or Lag and create new column. Then based on the values of that column, remove values from existing column
Names Default To Here(1);

dt = New Table("Untitled",
	Add Rows(11),
	Compress File When Saved(1),
	New Column("Column 1",
		Numeric,
		"Continuous",
		Format("Best", 12),
		Set Values([4.1, 3.4, 3.4, 3.4, 5.1, 2.6, 4.1, 3.4, 7.2, 7.2, 7.2])
	)
);

dt << New Column("ToDelete", Numeric, Nominal, << Set Each Value(
	Dif(:Column 1) == 0
));
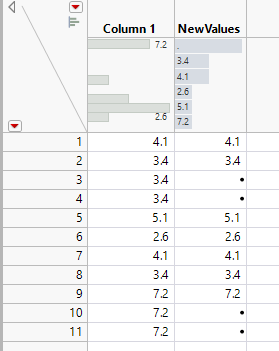
Or you can create new column with values (IfMZ is used to keep first row)
Names Default To Here(1);

dt = New Table("Untitled",
	Add Rows(11),
	Compress File When Saved(1),
	New Column("Column 1",
		Numeric,
		"Continuous",
		Format("Best", 12),
		Set Values([4.1, 3.4, 3.4, 3.4, 5.1, 2.6, 4.1, 3.4, 7.2, 7.2, 7.2])
	)
);

dt << New Column("NewValues", Numeric, Nominal, << Set Each Value(
	IfMZ(Dif(:Column 1) == 0,
		.
	,
		:Column 1
	)
));
-Jarmo
Recommended Articles
- © 2026 JMP Statistical Discovery LLC. All Rights Reserved.
- Terms of Use
- Privacy Statement
- Contact Us