cancel
Showing results for 
Show  only  | Search instead for 
Did you mean: 
  • Don’t miss your chance to experience Discovery Summit Europe at our best available rate! Early bird registration through 31 Oct.
  • Graph Builder Toolbar streamlines interactive graphing. Creates shortcuts on Report and GraphBuilder Helpers toolbars. Download and install the extension.
  • JMP will suspend normal business operations for our Rest and Recharge Day on Friday, October 2, 2026.
    Regular business hours will resume on Monday, October 5, 2026.

Discussions

Solve problems, and share tips and tricks with other JMP users.
Choose Language Hide Translation Bar
S_Boilermaker
Level II

Consolidating Repeated Values

I have a table like this with an ID number and a value assigned to each. Some ID numbers were tested multiple times and so have multiple values. I've seen codes to remove all rows with duplicate ID numbers, but I'd like a code that deletes all rows with duplicate ID's BUT saves the value from the nth test under a new column (e.g. value 2, value 3, value n)...


Any help would be greatly appreciated. Below is an example of before and what I would like after.

S_Boilermaker_0-1718048662396.png

S_Boilermaker_1-1718049072147.png


1 REPLY 1
txnelson
Super User

Re: Consolidating Repeated Values

Easy task

Create a new column.  I called it Sequence and give it the Formula

Col Cumulative Sum(1, :ID)

It will give a sequence number for each row for each separate ID it finds

txnelson_0-1718052245330.png

Now all that has to be done is to use the Split platform to split the data into new columns

     Tables=>Split
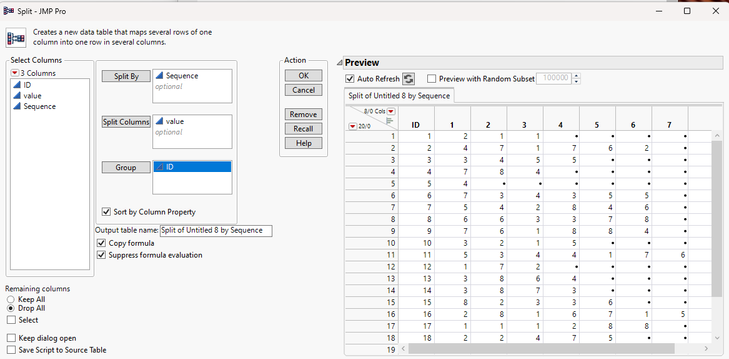
txnelson_1-1718052357331.png

Click on OK and it will create a new data table

txnelson_2-1718052406912.png


Jim

Recommended Articles