- Don’t miss your chance to experience Discovery Summit Europe at our best available rate! Early bird registration through 31 Oct.
- Graph Builder Toolbar streamlines interactive graphing. Creates shortcuts on Report and GraphBuilder Helpers toolbars. Download and install the extension.
- JMP will suspend normal business operations for our Rest and Recharge Day on Friday, October 2, 2026.
Regular business hours will resume on Monday, October 5, 2026.
- Subscribe to RSS Feed
- Mark Topic as New
- Mark Topic as Read
- Float this Topic for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Discussions
Solve problems, and share tips and tricks with other JMP users.- User Community
- :
- Discussions
- :
- Re: Optimize the loop to run faster
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Optimize the loop to run faster
Hello,
Happy new year!
Is there a way to make the processing faster? I tried using it for each, and it did save some time. I'm trying to figure out if I can optimize using the Column formula
Here is my for loop. It takes a very long time to run over 1M iterations. Any advice?
For each();
Thanks.
Accepted Solutions

- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
Most likely I messed up matrix columns and rows at some point but I don't have time to fix them now and this isn't tested with larger dataset than the one provided
Names Default To Here(1);

dt = Open("$DOWNLOADS/Sample table.jmp", invisible);

dt << Clear Row States;
dt << Clear Column Selection;

cols = dt << get column group("Tests");
test_cols = Transform Each({col}, cols, col << get name);

testcol_count = N Items(test_cols);
FUDDnum = Round(testcol_count * 0.17);


get_specs = Function({dt, colname}, {Default Local},
	colspec = Column(dt, colname) << get property("Spec Limits");

	specs = Associative Array();
	specs["LSL"] = Try(colspec["LSL"], .);
	specs["USL"] = Try(colspec["USL"], .);

	return(specs);
);

// set up pareto columns
yielditer = dt << Get Table Variable("YieldIteration");
If(yielditer == "",
	yield_iter_num = 1;
,
	yield_iter_num = Num(yielditer) + 1;
);
dt << Set Table Variable("YieldIteration", yield_iter_num);


NumFail = dt << New Column("FailureNumber" || yielditer, Numeric, <<Set Each Value(0));
PassCol = dt << New Column("PassFail" || yielditer, Numeric, << Set Each Value());
ParetoCol = dt << New Column("Pareto" || yielditer, Character, Nominal, Width(900),  <<Set Each Value("."));
dt << Group Columns({PassCol, ParetoCol, NumFail});


// get failing cells
m = J(N Items(test_cols), N Rows(dt), 0);
For Each({testcol, idx}, test_cols,
	specs = get_specs(dt, testcol);
	fail_rows = Loc(dt[0, testcol] < specs["LSL"] | dt[0, testcol] > specs["USL"]);
	m[idx, fail_rows] = 1;
);

dt[0, NumFail << get name] = V Sum(m)`;
dt[0, PassCol << get name] = Not(V Sum(m)` > 0);

For Each Row(dt,
	failcount = Column(dt, (NumFail << get name))[Row()];
	If(failcount > FUDDnum,
		ParetoCol[Row()] = "FUDD";
	, failcount > 0,
		fails = Loc(m[0, Row()]);
		ParetoCol[Row()] = Concat items(test_cols[fails], ", ");
	);
);
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
What are you attempting to do?
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
Most likely I messed up matrix columns and rows at some point but I don't have time to fix them now and this isn't tested with larger dataset than the one provided
Names Default To Here(1);

dt = Open("$DOWNLOADS/Sample table.jmp", invisible);

dt << Clear Row States;
dt << Clear Column Selection;

cols = dt << get column group("Tests");
test_cols = Transform Each({col}, cols, col << get name);

testcol_count = N Items(test_cols);
FUDDnum = Round(testcol_count * 0.17);


get_specs = Function({dt, colname}, {Default Local},
	colspec = Column(dt, colname) << get property("Spec Limits");

	specs = Associative Array();
	specs["LSL"] = Try(colspec["LSL"], .);
	specs["USL"] = Try(colspec["USL"], .);

	return(specs);
);

// set up pareto columns
yielditer = dt << Get Table Variable("YieldIteration");
If(yielditer == "",
	yield_iter_num = 1;
,
	yield_iter_num = Num(yielditer) + 1;
);
dt << Set Table Variable("YieldIteration", yield_iter_num);


NumFail = dt << New Column("FailureNumber" || yielditer, Numeric, <<Set Each Value(0));
PassCol = dt << New Column("PassFail" || yielditer, Numeric, << Set Each Value());
ParetoCol = dt << New Column("Pareto" || yielditer, Character, Nominal, Width(900),  <<Set Each Value("."));
dt << Group Columns({PassCol, ParetoCol, NumFail});


// get failing cells
m = J(N Items(test_cols), N Rows(dt), 0);
For Each({testcol, idx}, test_cols,
	specs = get_specs(dt, testcol);
	fail_rows = Loc(dt[0, testcol] < specs["LSL"] | dt[0, testcol] > specs["USL"]);
	m[idx, fail_rows] = 1;
);

dt[0, NumFail << get name] = V Sum(m)`;
dt[0, PassCol << get name] = Not(V Sum(m)` > 0);

For Each Row(dt,
	failcount = Column(dt, (NumFail << get name))[Row()];
	If(failcount > FUDDnum,
		ParetoCol[Row()] = "FUDD";
	, failcount > 0,
		fails = Loc(m[0, Row()]);
		ParetoCol[Row()] = Concat items(test_cols[fails], ", ");
	);
);
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
It works, Jarmo. Thanks a lot. You are awesome :)

- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
Have you tried the Profiler within Debugger to determine where most of the time is spent?

- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
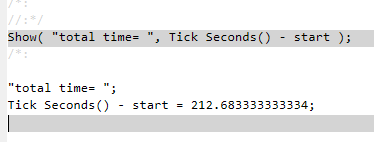
Here is the approach that I would take. I simplified the code to make the approach more obvious. On my system, each column is processed in 2.25 seconds or so.
Names Default To Here( 1 );
dt = Current Data Table();
start = Tick Seconds();
dt << Clear Row States;
dt << Clear Column Selection();

dt << Clear Column Selection;
allcol = dt << get column names( string );
dt << select column group( "Tests" );
selcol = dt << get selected columns;
dt << Clear Column Selection();

// loop thru each test, mark and count fails

//new for each loop
For Each( {ii, index}, selcol,
loopstart=tick seconds();
	If( ii << get data type == "Numeric",
	// set up pareto columns
		PassCol = New Column( "PassFail" || Char( index ), Numeric );
		colspec = ii << get property( "spec limits" );
		lsl = colspec["LSL"];
		usl = colspec["USL"];
		dt << select where( lsl >= ii <= usl );
		PassCol[dt << get selected rows] = 1;
		dt << invert row selection;
		PassCol[dt << get selected rows] = 0;
	);
	show("loop " || char(index), tick seconds - loopstart);
);
show("total time= ", tick seconds()-start);- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Get Direct Link
- Report Inappropriate Content
Re: Optimize the loop to run faster
Recommended Articles
- © 2026 JMP Statistical Discovery LLC. All Rights Reserved.
- Terms of Use
- Privacy Statement
- Contact Us